For businesses in Singapore and the Philippines that depend on organic search for lead generation, eCommerce revenue, and multilingual visibility, technical SEO has become less about surface-level audits and more about engineering decisions that influence crawl efficiency at scale. As websites grow into thousands or millions of URLs, the gap between what SEO teams believe search engines are crawling and what actually happens in server logs can widen quickly. That gap is where log file analysis becomes decisive. It exposes crawler behavior with precision, helps prioritise technical fixes, and gives SEO and engineering teams evidence they can act on before crawl waste turns into missed rankings, slower indexing, or incomplete coverage of revenue pages.
In 2026, high-traffic SEO programs are no longer judged only by keyword positions or content velocity. Decision-makers expect measurable control over crawl budget, indexation quality, canonical consistency, and server efficiency. Log file analysis gives that control because it shows every request search engine bots make to the site, including frequency, path depth, response codes, timing patterns, and crawler segmentation by user agent. For regional brands operating across different device types, languages, and infrastructure setups, that visibility matters. It helps technical teams understand whether Googlebot spends time on parameterized URLs, whether important commercial pages receive sufficient crawl attention, and whether infrastructure issues are creating hidden friction in discovery and rendering.
Why log files matter more when organic traffic scales
At smaller site sizes, SEO teams can often rely on crawl tools, sitemap reviews, and index coverage reports. Those sources remain useful, but they are still approximations. A crawler simulation can show what a tool can reach. Search Console can show aggregate search engine signals. Neither tells you with full certainty how often bots actually request each URL, what sequence they follow, or how response behavior changes under real server conditions. Log file analysis fills that gap by showing actual bot activity at the origin server level.
For high-traffic websites, this distinction is critical because crawl demand is not infinite. Search engines allocate crawl resources based on many factors, including site reputation, server performance, internal linking, URL uniqueness, and historical response behavior. If a website generates too many low-value URLs, such as filtered categories, internal search results, or stale parameter combinations, bots may spend proportionally more time on pages that never convert. That can delay discovery of new product pages, updated pricing, local landing pages, or fresh editorial assets that matter to the business.
What log analysis reveals that other tools miss
Log analysis reveals patterns that surface-level audits frequently miss. You can see crawl bursts after content updates, identify recurring hits to non-canonical URLs, confirm whether robots directives are respected in practice, and detect bot activity on pages that should no longer exist. It also helps teams differentiate between Googlebot smartphone, Googlebot image, Bingbot, and other agents so they can assess channel-specific behavior rather than relying on generic assumptions.
For example, if a regional retail site in Singapore launches a new category architecture for promotional campaigns, logs can show whether bots are prioritizing the new structure or continuing to spend resources on obsolete filtered paths. That distinction affects indexing latency and the speed at which new revenue pages become visible in search. The same applies to Philippine publishers or marketplaces with frequent content updates, where freshness can be a direct ranking and revenue factor.
The mechanics of a modern log file analysis workflow
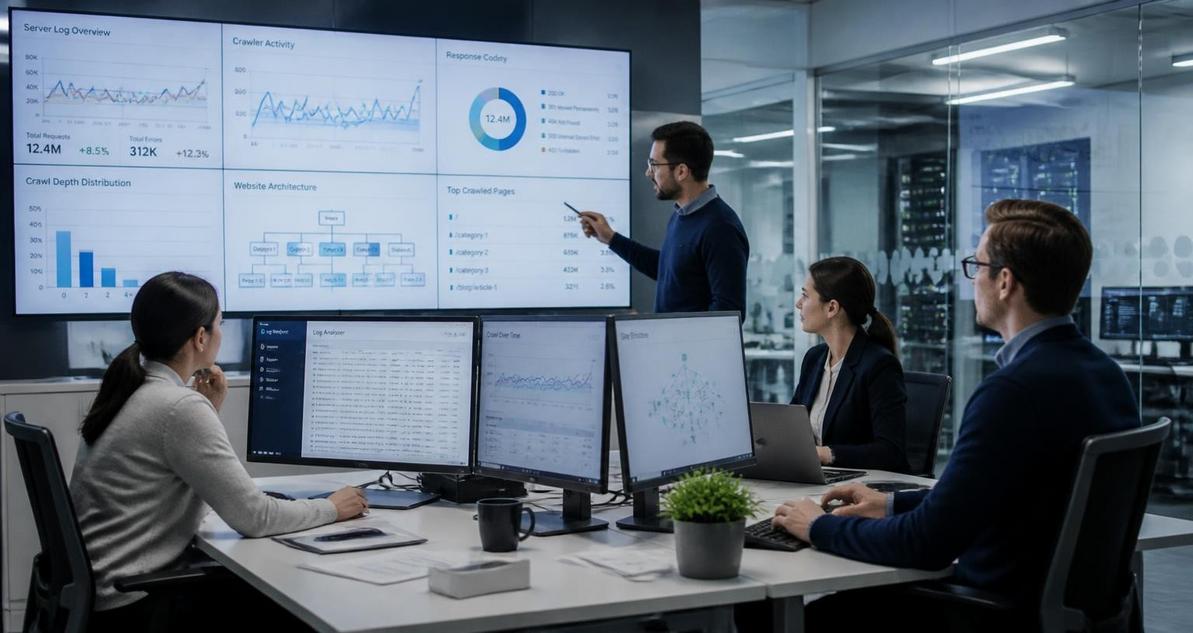
Effective log analysis in 2026 requires more than opening raw files in a spreadsheet. High-volume environments demand structured ingestion, bot classification, enrichment, and correlation with site architecture data. The objective is not just to count hits. The objective is to answer operational questions: which bots request which URLs, how often, in what sequence, with what status codes, and at what performance cost?
A typical workflow starts by collecting logs from web servers, load balancers, CDN edge layers, or cloud storage buckets. Depending on the stack, relevant records may come from Apache, Nginx, cloud hosting platforms, or a CDN such as Cloudflare or Akamai. Teams then normalize the data, remove noise, identify verified bots, and map requests to canonical URL sets, templates, and business priorities. At this stage, segmentation is essential. A product detail page, a category listing, a support article, and a faceted filter endpoint should not be evaluated with the same crawl assumptions.
Segmentation and bot verification
Bot verification is one of the most important parts of the process. User-agent strings alone are not enough because they can be spoofed. Verified bot activity should be cross-checked through reverse DNS, IP validation, or trusted vendor lists when available. This matters for trustworthy analysis because decisions based on fake crawler traffic can lead to the wrong technical priorities. Once verified, teams can separate major crawlers and inspect how each behaves across the same URL groups.
Segmentation should also include HTTP status grouping. A surge in 3xx responses may indicate redirect chains or architecture changes that need consolidation. Repeated 4xx responses can point to orphaned links, stale XML sitemap entries, or deleted pages that still attract crawl demand. Excessive 5xx responses, even if intermittent, are especially harmful because they can reduce crawler confidence and delay recrawling of important sections.
How high-traffic SEOs use logs to improve crawl efficiency
The most valuable use of log analysis is operational prioritization. High-traffic SEO teams do not fix everything at once. They focus on changes that improve crawl efficiency and indexation quality at the URL groups that drive revenue, authority, or user retention. Logs give them the evidence to rank those actions by impact.
One common use case is spotting crawl waste caused by faceted navigation. Large eCommerce catalogs often generate thousands of URL variations through color, size, sort order, and filter parameters. If crawler activity shows that search engines repeatedly hit low-value combinations instead of canonical product or category URLs, the SEO team can adjust internal linking, canonicalization, noindex rules, robots directives, or parameter handling strategies. The key point is that logs expose the actual crawl behavior, not the intended behavior.
Another use case is testing whether XML sitemaps are doing their job. A sitemap is only useful if search engines are actually discovering and recrawling the included URLs. By comparing sitemap-included URLs against log frequency, teams can see whether priority pages receive enough attention after updates. If important landing pages are submitted but rarely crawled, the issue may be weak internal linking, poor crawl paths, excessive depth, or competing low-value URLs that dilute bot attention.
Internal linking and crawl path analysis
Logs also help reveal crawl paths through the site. If a revenue-critical page sits four or five clicks from the homepage and receives little bot attention, internal linking may need to be redesigned. In practice, this means examining the routes bots take from high-authority sections into deeper templates. This matters for businesses with large content hubs, multilingual site versions, or country-specific landing pages across Singapore and the Philippines, where architecture often grows quickly and inconsistently.
Internal linking signals are particularly important after site migrations or redesigns. During a migration, logs can show whether bots follow old URL structures too long, whether redirects are clean, and whether newly launched templates are receiving crawl parity with legacy pages. Teams that use logs early in a migration often detect problems before ranking losses become obvious in analytics.
Technical SEO decisions that become clearer with log data
Log analysis influences several technical decisions that directly affect organic visibility. One of the most important is canonical consistency. If bots keep requesting non-canonical versions of pages, such as parameterized URLs or obsolete variants, the site may be sending mixed signals that reduce indexing efficiency. Logs can confirm whether canonical tags are being respected in practice or whether crawl demand is still leaking into alternate paths.
Another important area is server performance. Crawl behavior and server response are linked. Slow response times can lower crawl throughput, especially on large sites. If logs show reduced crawl activity after spikes in latency or repeated 5xx patterns, SEO and engineering teams can connect the dots between backend performance and search visibility. That connection matters in environments where infrastructure changes, seasonal demand spikes, or third-party API dependencies can affect crawlability.
Log analysis also supports international SEO. For brands targeting Singapore and the Philippines, language versions, country-specific paths, and duplicated templates can create complex crawl patterns. Logs help confirm whether regional pages receive the crawl frequency they deserve and whether bots spend unnecessary time on duplicate language or locale variants. This is especially useful when hreflang implementation, localization rules, and site architecture must work together.
Indexation validation and content freshness
Content freshness is another area where logs create clarity. A page can be updated in the CMS, but if crawlers do not revisit it quickly enough, the update may not influence search performance when expected. By comparing publish dates, lastmod signals, and actual crawl timestamps, teams can estimate whether recrawl cadence aligns with content importance. That insight helps editorial teams, product teams, and SEO leads coordinate release timing around launches, campaigns, or seasonal demand.
For newsrooms, marketplaces, and fast-moving B2B websites, crawl freshness can shape visibility for time-sensitive pages. Logs reveal whether crawler attention increases after internal linking changes, homepage placement, or sitemap updates. They also show which sections are effectively dormant, allowing teams to decide whether those pages need stronger linking, consolidation, or removal.
Practical industry applications for Singapore and Philippines teams
In Singapore, where many brands operate in highly competitive finance, technology, and professional services sectors, log file analysis is especially useful for managing dense site structures and multilingual assets. Corporate sites often accumulate investor pages, service landing pages, event hubs, resource libraries, and campaign microsites. Without log analysis, it becomes difficult to determine whether search engines are prioritising the pages that support pipeline generation or spending time on older campaign artifacts.
In the Philippines, log analysis supports large-scale publishing, retail, and marketplace environments where traffic spikes can be volatile and content turnover is fast. For publishers, logs help separate crawl demand for evergreen editorial assets from low-value archive pages. For retail brands, they help identify whether seasonal collection pages are being crawled early enough to support campaign timing. For B2B lead generation sites, they help confirm whether gated assets, service pages, and location-specific landing pages are being discovered before paid media spend ramps up.
A useful real-world pattern appears during major site refreshes. If a business introduces a new template but keeps old taxonomy structures live, logs can show that bots continue favoring legacy paths. That behavior often explains why some redesigns underperform despite strong content. The technical issue is not only the design. It is the crawl path. By reading logs before and after deployment, teams can test whether the new structure actually receives crawler attention or whether supporting changes are needed.
Implementation checklist for log file analysis in 2026
To make log analysis operational rather than occasional, SEO, analytics, and engineering teams should build a repeatable framework that fits their infrastructure and reporting cadence.
- Collect logs from all relevant layers, including origin servers, CDN edges, and load balancers when possible.
- Verify crawler identity using trusted validation methods instead of user-agent strings alone.
- Normalize URL data by mapping parameters, canonical variants, trailing slashes, and uppercase or lowercase differences.
- Segment by bot type, status code, and template class so analysis reflects business priorities rather than raw volume.
- Compare crawl demand with sitemap inclusion to detect priority URLs that are undercrawled.
- Review redirect chains and error rates to identify crawl waste and infrastructure issues.
- Correlate logs with deployment events after migrations, template changes, content launches, and robots updates.
- Track recrawl frequency for important pages so freshness and indexing expectations stay realistic.
- Use findings to refine internal linking, canonicalization, and parameter handling rather than treating logs as a reporting exercise only.
- Store and compare historical logs so trend analysis can reveal whether technical changes actually improved crawler efficiency over time.
Teams that treat log file analysis as a standing discipline rather than a periodic audit usually make better technical decisions because they can prove what search engines are doing at scale. That evidence changes conversations with developers, stakeholders, and leadership because it replaces assumptions with crawler behavior that can be measured, filtered, and acted on.
I am Tricia Huang Mei, an Advertising Partner in Sotavento Medios with over two decades of experience in the Singapore advertising and business sectors. My career is defined by a commitment to driving high-impact marketing campaigns and fostering sustainable growth for the diverse business portfolios I manage.