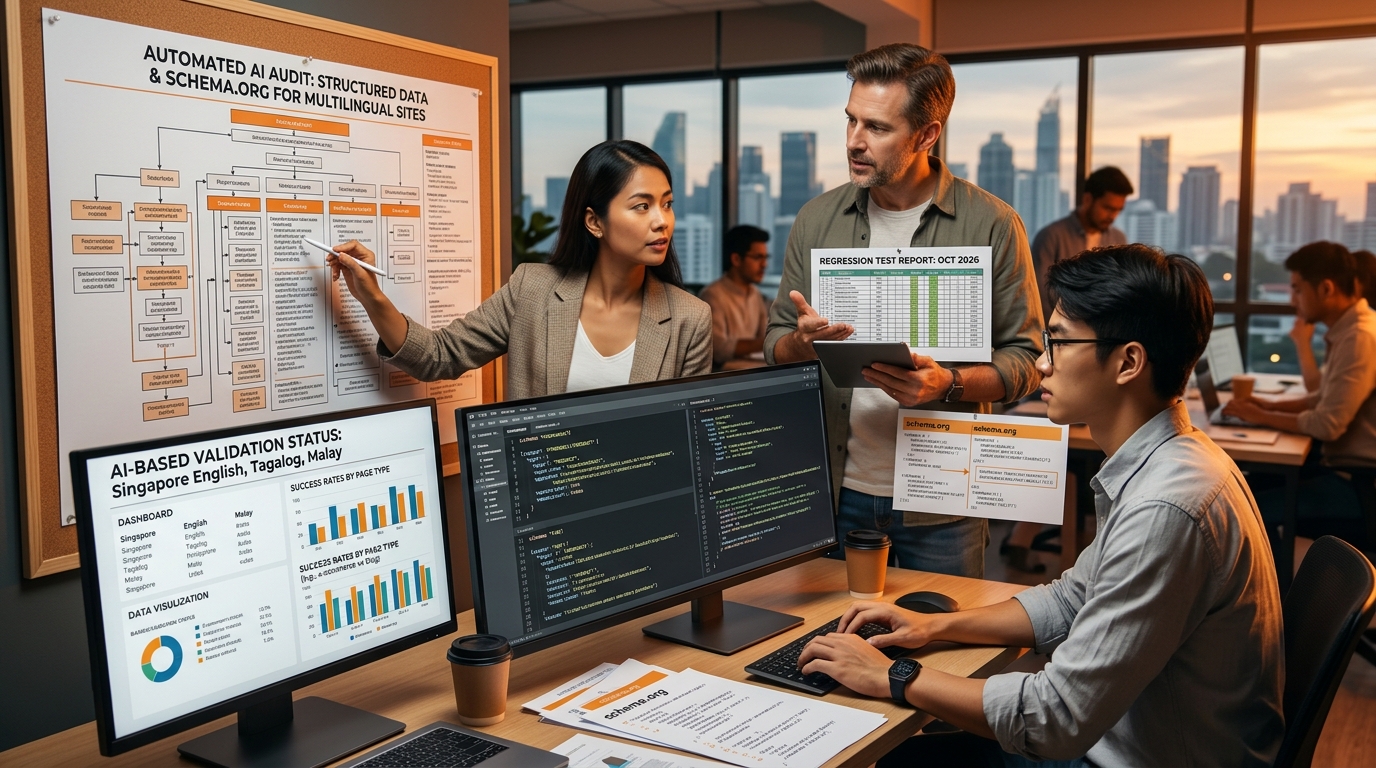
For businesses in Singapore and the Philippines, structured data has become more than an SEO enhancement. It now supports product visibility, rich results eligibility, local search performance, and machine-readable context for search engines, AI assistants, and enterprise knowledge systems. As more commerce, service, and B2B discovery happens through search surfaces that interpret schema markup, the cost of broken, incomplete, or inconsistent structured data keeps rising. Teams that operate across multiple websites, regional landing pages, language variants, or CMS environments need a reliable way to detect schema regressions before they affect indexing and click-through performance. Automated AI testing suites give technical marketing teams a scalable method to validate structured data at deployment speed, not after search visibility has already declined.
Traditional spot checks in Google Rich Results Test or Schema Markup Validator are useful, but they do not provide continuous assurance across large page sets or multi-environment release cycles. Automated AI testing suites fill that gap by combining rule-based validation, machine learning-assisted anomaly detection, and workflow integration into CI/CD pipelines. For enterprise teams, this means structured data can be audited like any other production dependency. When schema quality becomes part of the release process, teams reduce risk, improve governance, and maintain eligibility for search features that depend on clean semantic markup.
Why Structured Data Audits Matter in High-Volume Digital Environments
Structured data is often implemented once and then forgotten until traffic drops or a search result stops showing enhanced features. That approach does not scale for businesses running hundreds or thousands of templates across product pages, branch pages, articles, service pages, and local store listings. In Singapore and the Philippines, where multilingual content, franchise structures, and multi-location discoverability are common, even a small schema inconsistency can affect the accuracy of business information in search. Search engines rely on structured data to confirm entities, attributes, and relationships, so errors such as missing required properties, invalid types, and conflicting canonical signals can reduce trust in the page.
Auditing structured data manually is not efficient when releases happen weekly or daily. A typical enterprise content stack may include custom templates, third-party plugins, headless CMS content models, and dynamically injected JSON-LD. Each of those layers introduces failure modes. A marketing team may change a page template and accidentally remove FAQPage markup. A product team may localize pricing content without updating Offer fields. A developer may refactor scripts and alter object nesting in a way that still renders valid HTML but invalid JSON-LD. Automated AI testing suites help detect these issues before they reach production search crawlers.
Common structured data failure patterns
Most failures fall into a few recurring categories. Missing required fields are common, especially for Organization, Product, BreadcrumbList, and Article schemas. Incorrect nesting also appears frequently when developers reuse components but do not update item properties or @type declarations. Another common issue is duplication, where the same entity is declared multiple times with conflicting values across page source, tag managers, and CMS plugins. AI-assisted testing helps identify these patterns across large samples, not only on pages already known to have manual errors.
What Automated AI Testing Suites Actually Do
An automated AI testing suite for structured data combines multiple layers of inspection. The baseline layer parses JSON-LD, Microdata, or RDFa and verifies syntax against schema definitions and schema.org expectations. The next layer checks semantic correctness, such as whether an Article has a valid author entity or whether a Product page includes coherent offer details. The AI layer then looks for anomalies, patterns, and regressions across sets of pages, which is especially useful when schema is generated dynamically from templates or data feeds.
These suites often connect to source control, staging environments, and production URLs. They can crawl page sets, extract structured data blocks, compare them against previous snapshots, and flag unexpected differences. If a page template changes and removes nested properties from 400 category pages, the system should surface that as a release issue rather than a manual QA task after deployment. This is where AI adds value beyond deterministic validation. A rules engine can tell you a required property is missing, but an AI model can also identify that your markup is structurally inconsistent with similar pages in the same template family.
Rule-based checks versus AI-assisted checks
Rule-based checks are precise. They validate known requirements, such as property presence, value format, and type compatibility. They are ideal for enforcing schema policies, especially when teams need predictable pass or fail outcomes. AI-assisted checks add another layer by comparing markup patterns across page clusters and flagging outliers. For example, if every service page on your Singapore website includes LocalBusiness markup with geo coordinates, but one branch page suddenly loses that field after a CMS update, the AI layer can identify that deviation even if the page still passes basic syntax validation.
The strongest testing suites combine both approaches. Relying only on AI is risky because semantic models can miss exact specification issues. Relying only on rules can produce brittle coverage when markup structures vary across templates. A hybrid model creates a more resilient audit framework. It gives technical teams a way to enforce standards while also detecting low-signal drift that would be expensive to catch manually.
How to Build an Automated Audit Workflow for Structured Data
To audit structured data effectively, start by defining the inventory. Identify which page types carry schema, which schema types matter for search visibility, and which templates generate them. In a B2B environment, that often includes homepage markup, service pages, blog posts, webinar pages, case studies, location pages, and product pages. Map each template to the schema types it should support, then define required and recommended fields for each use case. This creates the testing baseline before any tool is configured.
Next, connect your structured data tests to your delivery pipeline. Teams using GitHub Actions, GitLab CI, Jenkins, or similar systems can run schema audits on every pull request or staging deployment. At minimum, test for syntactic validity, schema type presence, required properties, and canonical alignment. More advanced checks should compare rendered HTML against extracted JSON-LD, verify that structured data matches visible content, and confirm that business entities are consistent with your knowledge graph or CRM source of truth.
Set thresholds and severity levels
Not every issue should block a release, but every issue should be visible. Define severity categories such as critical, major, and informational. A critical issue might be invalid JSON-LD that breaks rich result eligibility. A major issue might be missing required offer details on a commercial page. An informational issue might be an optional field that could improve completeness but does not prevent indexing. Severity scoring helps marketing, SEO, and engineering teams prioritize what must be fixed before deployment and what can enter the backlog.
It is also useful to create page-level and site-level thresholds. A single broken article page may be acceptable as an isolated incident. A recurring failure across 30 product templates is a release blocker. Automated AI testing suites should report both the individual defect and the affected pattern, because pattern-level insight is what allows teams to fix root causes, not just symptoms.
Using AI to Detect Semantic Drift and Template Regression
One of the most valuable uses of AI in structured data auditing is drift detection. Semantic drift happens when the markup still exists, but the meaning or completeness changes over time. A service page may retain its Service schema while losing the provider name. A blog template may still output Article markup, but the author entity may switch from a person object to a plain string. These issues are hard to spot with traditional QA because the page may still look correct in the browser.
AI testing suites can compare page groups over time and identify when properties disappear, change type, or deviate from established template norms. This is especially useful for organizations with regional content operations across Singapore and the Philippines, where pages may be duplicated, translated, or adapted for local markets. A strong audit process should verify that localized pages preserve required semantic structure while allowing legitimate region-specific differences such as language, address, or service area. AI can help distinguish intended variation from accidental regression.
Practical example from a multi-location business
Consider a company with offices in Singapore, Manila, Cebu, and Makati, each with separate location pages and local business schema. A release introduces a new page component, and one office page loses its geo coordinates while another receives the wrong telephone format. A conventional crawl might only surface one invalid schema instance. An AI-assisted suite can detect that the issue is part of a broader deployment pattern affecting a component family. It can also highlight that the affected pages share a template revision, which helps engineering teams locate the root cause faster.
This same approach applies to B2B publishers and SaaS companies. If a webinar schema template no longer outputs event dates correctly after a timezone handling change, AI-based regression tests can identify the anomaly before search engines crawl the affected page set. That kind of early detection protects campaign traffic and reduces the chance of sending users to pages with misleading metadata.
Metrics, Reporting, and Governance for Ongoing Control
Structured data auditing should produce metrics that both technical and business stakeholders can act on. Useful reporting dimensions include pass rate by template, error rate by schema type, number of pages affected, time to remediation, and recurrence of the same issue across releases. Over time, these metrics show whether the content system is becoming more stable or more fragile. They also help justify engineering investment by linking schema quality to operational discipline.
Governance matters because structured data often spans SEO, content, development, and analytics teams. Assign ownership for each schema category and define who approves changes to shared templates. Keep a versioned policy document that states which schema types are approved, which properties are mandatory, and which product or content teams own updates. Store test fixtures in source control so new templates are validated against known-good examples. When teams treat structured data as governed infrastructure, audits become part of normal delivery rather than a crisis response activity.
Trustworthiness also depends on validation against official references. Schema.org should remain the primary vocabulary reference, while Google Search Central documentation should guide eligibility expectations for rich results. If your implementation supports multiple search engines or downstream consumers, test against their documented requirements separately. Do not assume that a schema pattern accepted by one platform will behave identically elsewhere. An audit framework should distinguish between standards compliance and platform-specific eligibility.
Technical Implementation Checklist for Automated Structured Data Audits
Use the following implementation sequence to operationalize automated audits in a production environment.
- Inventory every template that emits structured data, including localized and dynamically generated pages.
- Define the required schema types and mandatory properties for each page category.
- Validate current markup against schema.org and platform-specific guidelines.
- Set up automated extraction of JSON-LD, Microdata, or RDFa from rendered pages.
- Run syntax checks, type checks, and required-field checks on every deployment.
- Add snapshot comparisons to detect regressions across template versions.
- Use AI-assisted anomaly detection to flag semantic drift and outlier pages.
- Assign severity levels and release-blocking rules for critical failures.
- Route alerts to the correct owner, such as SEO, engineering, or content operations.
- Store audit outputs and historical results for trend analysis and governance.
- Review high-impact pages weekly, and review template-level results on every release.
For businesses in Singapore and the Philippines, this workflow creates a practical control system for maintaining structured data quality across fast-moving digital properties. It supports larger content operations, improves confidence in search-facing metadata, and reduces the risk of schema regressions introduced by routine releases. When teams combine deterministic checks with AI-assisted pattern analysis, they can audit structured data at the pace modern publishing requires.
I am Tricia Huang Mei, an Advertising Partner in Sotavento Medios with over two decades of experience in the Singapore advertising and business sectors. My career is defined by a commitment to driving high-impact marketing campaigns and fostering sustainable growth for the diverse business portfolios I manage.