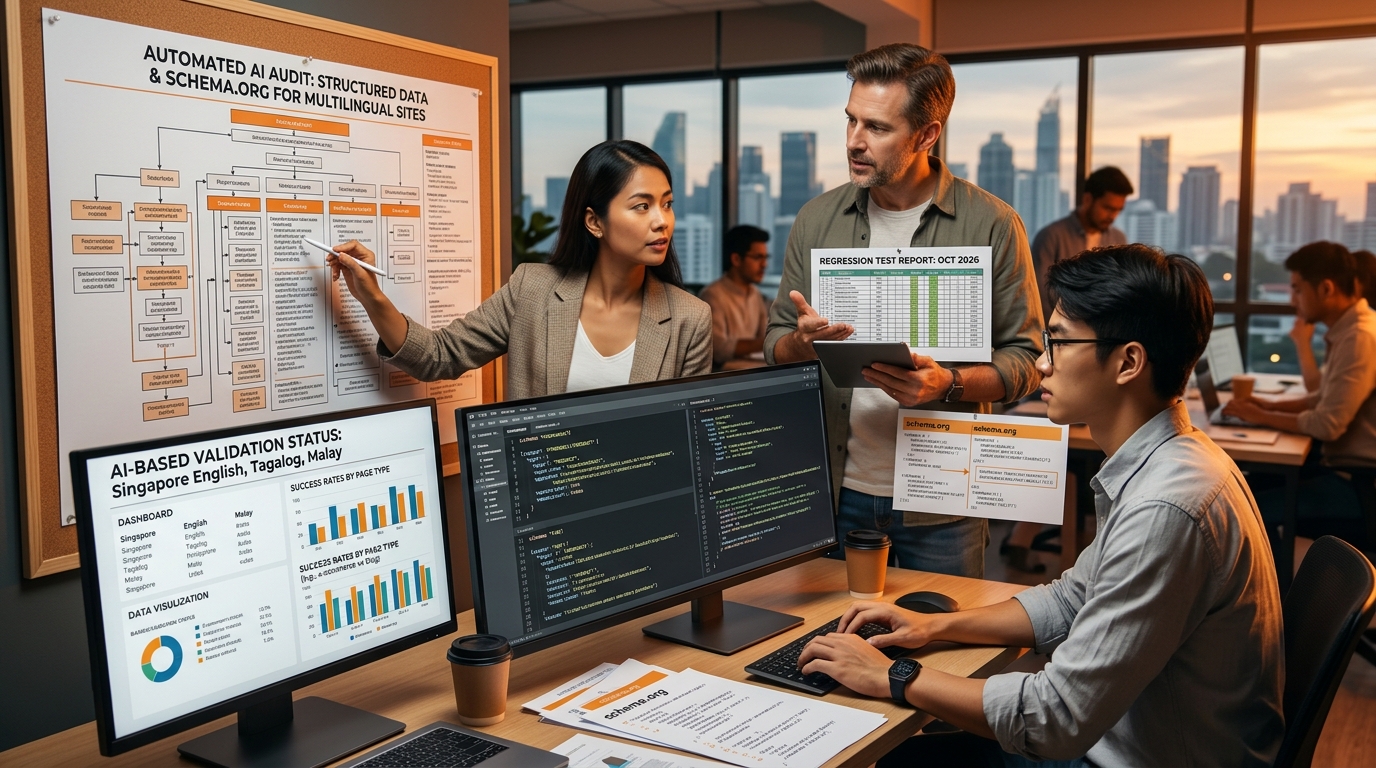
For businesses in Singapore and the Philippines, structured data is no longer a niche SEO enhancement. It directly affects how products, services, locations, events, FAQs, and company entities appear in search engines, AI answers, and discovery surfaces used by B2B buyers. When a schema markup implementation breaks, the impact is rarely visible in code alone, but the downstream effects can show up in reduced eligibility for rich results, weaker entity understanding, and inconsistent presentation across search interfaces. This is why technical teams increasingly treat structured data auditing as part of release engineering, not just SEO maintenance. Automated AI testing suites now make that possible by combining validation rules, machine-assisted anomaly detection, and regression testing across templates, locales, and deployment cycles.
For organizations operating across multilingual markets, multiple domains, or complex site architectures, manual checks are not enough. A single template change can alter JSON-LD output across hundreds of pages, and a CMS update can silently strip required properties such as @type, name, or aggregateRating. Automated AI testing suites help technical marketers, developers, and QA teams detect these failures before they affect crawlability or search visibility. They also make structured data governance more scalable by turning schema validation into a repeatable testing discipline.
Why structured data audits need automation in B2B environments
Structured data auditing used to rely on spot checks in Google’s Rich Results Test, Schema Markup Validator, and browser console inspection. Those tools remain useful, but they are not enough for modern enterprise websites with dynamic content, A/B testing, and frequent deployments. A B2B website with multiple service lines, location pages, case study libraries, and knowledge content can produce thousands of structured data nodes across different templates. Checking them manually creates blind spots, especially when teams push updates weekly or run separate front-end and CMS release pipelines.
Automated AI testing suites solve this by running schema checks as part of a broader test layer. Instead of validating a few sample pages, they can crawl page sets, parse JSON-LD, compare outputs against expected schema models, and flag structural drift. AI components add value when they identify anomalous changes that rule-based tests may miss, such as sudden property loss, mismatched entity types, inconsistent sameAs references, or page-level schema patterns that differ from historical baselines. For agencies and in-house teams supporting Singapore and Philippines markets, this matters because many websites localize content, language variants, and business information across regional directories. A data model that works for one market may fail in another if addresses, contact points, or organization references are not normalized.
Automation also supports governance. Search engine guidance changes over time, and structured data standards evolve with schema.org updates and rich result eligibility policies. If a team relies on ad hoc reviews, technical debt accumulates quickly. A testing suite creates a consistent audit trail and gives stakeholders confidence that structured data remains valid after each release.
What an automated AI testing suite should inspect
A strong structured data testing suite should do more than confirm that JSON-LD parses. It must validate schema integrity, semantic correctness, and operational consistency across environments. The audit should combine syntax checks, field-level assertions, and behavior-based analysis. That means evaluating whether the markup is technically valid, whether it matches the visible page content, and whether it conforms to the search intent of the page type.
Syntax and schema compliance
At the foundation, the suite should verify that JSON-LD is well-formed and that schema types use valid properties. This includes checking for malformed brackets, duplicate keys, invalid data types, and unsupported combinations. It should also validate nested objects, such as Organization, BreadcrumbList, Product, LocalBusiness, Article, FAQPage, and Service. For pages with multiple schema blocks, the suite should ensure that each block serves a distinct purpose and does not conflict with another entity definition.
A practical audit rule is to define schema contracts by template. For example, a service landing page may require Service, Organization, BreadcrumbList, and WebPage entities, while a location page may require LocalBusiness, PostalAddress, OpeningHoursSpecification, and sameAs references. The test suite should enforce these contracts every time the page builds.
Entity relationships and canonical consistency
Search engines interpret structured data as an entity graph, not as isolated snippets. That makes relationship validation essential. The suite should confirm that the author, publisher, and organization references resolve consistently across the site. It should also verify that canonical URLs, @id values, and URL properties point to the correct canonical resource. In enterprise environments, this matters because the same organization may appear in multiple subdomains, regional sites, or microsites. If the entity graph fragments, search engines may treat them as separate or conflicting identities.
AI-driven testing adds value here by identifying patterns in mismatched identifiers. For example, if the same organization name appears with different @id values across templates, the suite can flag a likely identity fragmentation issue. This is especially useful when teams use headless CMS platforms, server-side rendering, or component-based front ends where the schema output is assembled from several data sources.
Content parity and semantic alignment
Structured data must match visible page content. A common failure mode occurs when editors update headlines, pricing, product availability, office hours, or service areas on the page but the schema remains unchanged. Search engines treat this as low-trust markup, and rich result eligibility can be reduced if the markup appears misleading. Automated AI testing suites can compare visible DOM content with structured data fields and identify mismatches in names, dates, descriptions, or availability states.
For example, a Philippine B2B software provider may update its consultation hours on the page but forget to update OpeningHoursSpecification in JSON-LD. A good test suite should catch this discrepancy during staging validation. Similarly, if a Singapore office page lists a new phone number in the footer but not in LocalBusiness, the suite should report the inconsistency before deployment.
How to design a structured data audit workflow with AI testing
Auditing structured data effectively requires a workflow that fits the development lifecycle. The best approach is to move from static validation to continuous testing. That means establishing baselines, automating checks in CI/CD, and using AI to surface anomalies at scale. This workflow should serve both SEO and engineering teams so that structured data quality becomes a shared responsibility.
Step 1: Build a schema inventory
Start by cataloging every page type that uses structured data. Group pages by template, not by individual URL. Include service pages, blog posts, case studies, pricing pages, location pages, contact pages, and FAQ resources. For each template, define the expected schema types, required properties, optional properties, and business rules. This inventory becomes the source of truth for automated tests.
In practice, the inventory should include fields such as page template, schema type, required entity names, canonical URL pattern, locale rules, and visible content dependencies. If your site serves both English and localized versions, note where structured data changes by language or region. This prevents false positives later when the test suite compares output across versions.
Step 2: Create machine-readable assertions
Next, convert the inventory into assertions that a test runner can evaluate. These assertions should check for presence, format, and relationship integrity. Examples include verifying that every service page contains Service schema, every organization block includes a valid sameAs set, and every article includes headline, datePublished, dateModified, and author. Assertions should also enforce business rules such as unique @id values, valid URLs, and no duplicate organization entities on the same page unless intentional.
AI systems improve this layer by recognizing template drift. A rules engine may confirm that Product schema exists, but an AI classifier can detect that the page content now resembles a Service page and that the schema type no longer matches the page intent. This is important for sites that repurpose landing pages or use modular content blocks across different offers.
Step 3: Integrate into CI/CD and staging review
Structured data tests should run in staging and pre-production environments before release. The suite can crawl the staging site, extract JSON-LD, compare it against baseline snapshots, and fail the build if critical errors appear. Teams using Git-based deployment pipelines can attach these checks to pull requests so that developers see schema regressions before merge. This approach is especially valuable for organizations with distributed teams across Singapore and the Philippines, where deployment windows may vary and coordination costs are high.
A useful practice is to separate failures into severity tiers. Critical issues include malformed JSON-LD, missing required fields for rich result eligibility, and broken entity references. Warning-level issues include missing optional fields, inconsistent descriptions, or non-critical property drift. This helps development teams prioritize remediation without blocking releases unnecessarily.
Step 4: Use AI for anomaly detection and pattern comparison
AI testing is most useful when it detects unusual deviations from historical patterns. For example, if hundreds of pages suddenly lose structured data after a CMS plugin update, AI-assisted monitoring can identify the scope faster than manual review. It can also highlight subtle anomalies, such as a recurring drop in breadcrumb completeness on a specific template or a spike in invalid date formats after content migration.
To make this work, train the suite on template-level baselines. The system should know what a normal schema output looks like for each page class and flag departures from that model. The goal is not to replace deterministic validation, but to add contextual awareness. In large websites, this reduces noise and helps teams focus on structural issues rather than isolated one-off errors.
Common failure patterns found during structured data audits
Even well-managed sites develop structured data defects over time. The most common issue is schema-content mismatch. This occurs when the markup no longer reflects the actual page content, often due to editorial updates, A/B testing, or partial CMS publishing. Another frequent problem is incomplete markup on templates that depend on dynamic data, such as missing aggregateRating values on product pages or absent address fields on location pages.
Duplicate schema is another recurring issue. This happens when multiple plugins, theme components, or scripts emit overlapping JSON-LD blocks. Search engines may ignore some of the data or interpret the page inconsistently. Canonical confusion is also common, particularly when the same entity is referenced with different URL variants, trailing slashes, or parameterized URLs. In multilingual websites, the risk increases because hreflang, canonical tags, and schema URLs must align precisely.
Organizations in regulated or reputation-sensitive sectors should also watch for outdated organizational facts. Phone numbers, office addresses, service areas, legal names, and social profile links often drift across properties. If these fields are inconsistent across the footer, contact page, and Organization schema, the audit should flag them for correction. Automated AI testing suites are especially effective here because they can compare structured data against source-of-truth datasets, not just against the page HTML.
Implementation checklist for production-grade structured data testing
To operationalize structured data audits, technical teams should establish a repeatable process that combines governance, automation, and release controls. The checklist below fits enterprise websites and agency-managed builds that require consistent quality across multiple templates and regional properties.
- Define structured data ownership across SEO, engineering, and content teams.
- Document every schema type used on the site, mapped by template and locale.
- Set required and optional properties for each schema contract.
- Validate JSON-LD syntax, entity relationships, and canonical references on every build.
- Compare structured data against visible page content to catch semantic drift.
- Run tests in staging and pre-production before pushing changes to production.
- Use AI anomaly detection to identify large-scale regressions and template drift.
- Track schema changes in version control and maintain change logs for audits.
- Re-test after CMS updates, redesigns, migrations, or plugin changes.
- Review search engine reports and structured data warnings as part of regular QA cycles.
A disciplined testing process makes structured data more reliable, more scalable, and easier to govern across complex digital ecosystems. For B2B teams in Singapore and the Philippines, the payoff is stronger technical SEO control, cleaner release management, and better search interpretation across local and international markets.
I am Tricia Huang Mei, an Advertising Partner in Sotavento Medios with over two decades of experience in the Singapore advertising and business sectors. My career is defined by a commitment to driving high-impact marketing campaigns and fostering sustainable growth for the diverse business portfolios I manage.